
FuturPulse analysis · 19 October 2026
DeepSeek’s May 2026 cut was real, but its current direct API schedule is higher for every comparable V4-Pro billing category. The important qualification is model version and timing: the current official page names DeepSeek-V4-Pro-0813 and uses separate peak and off-peak prices. Reuters reported that DeepSeek made the 75% V4-Pro reduction permanent in May. (api-docs.deepseek.com)
At a glance
- DeepSeek’s direct V4-Pro API lists $0.66 per million uncached input tokens and $1.98 per million output tokens off-peak.
- The direct peak schedule doubles those rates to $1.32 for uncached input and $3.96 for output per million tokens.
- May reporting put the permanent V4-Pro rate at $0.435 for uncached input and $0.87 for output per million tokens.
- By our calculation, an uncached 30,000-input, 2,000-output agent step costs $23.76 per 1,000 calls off-peak today.
Did DeepSeek actually hike V4-Pro prices
Yes, if “DeepSeek Pro” means the direct DeepSeek-V4-Pro API. DeepSeek’s current pricing page lists $0.022 per million cache-hit input tokens, $0.66 per million cache-miss input tokens and $1.98 per million output tokens during off-peak hours. (api-docs.deepseek.com)
The previous permanent rate was lower. InfoWorld’s account of DeepSeek’s May announcement put V4-Pro at $0.003625 for cache-hit input, $0.435 for uncached input and $0.87 for output per million tokens after the 75% reduction.
That makes the current off-peak uncached-input rate 51.7% higher than the reported May rate. The off-peak output rate is 127.6% higher. The cache-hit rate rose 506.9%, although cached prompts and newly introduced time bands make that comparison less clean.
| Concrete option | Input, cache hit per 1M | Input, cache miss per 1M | Output per 1M | What it means | Evidence tier |
|---|---|---|---|---|---|
| May 2026 permanent V4-Pro rate | $0.003625 | $0.435 | $0.87 | The rate buyers expected after the 75% cut. | Reported company statement |
| Direct API, current off-peak | $0.022 | $0.66 | $1.98 | The lowest currently published direct V4-Pro schedule. | Primary vendor page |
| Direct API, current peak | $0.044 | $1.32 | $3.96 | Use this budget if calls land in DeepSeek’s weekday peak periods. | Primary vendor page |
| OpenRouter V4 Pro 0423 | Not listed | $0.45 | $3.48 | A separate gateway price, not DeepSeek’s direct bill. | Reseller listing |
Tokens are the chunks of text a model reads and bills by. A cache hit means DeepSeek can reuse previously processed prompt material; a cache miss means it must process that input again.
How much does DeepSeek Pro cost?
DeepSeek-V4-Pro costs from $0.022 to $3.96 per million tokens on its direct API, depending on input versus output, cache status and time of use. The current vendor page says off-peak is all time outside weekday windows of 01:00–04:00 and 06:00–10:00 UTC, excluding Chinese public holidays. (api-docs.deepseek.com)
For a normal new prompt, the useful figures are $0.66 per million off-peak input tokens and $1.98 per million off-peak output tokens. Output is the model’s answer, so applications that generate long drafts, code or reasoning traces will feel the output increase most.
Do not confuse a gateway quote with DeepSeek’s own price. OpenRouter currently lists DeepSeek V4 Pro 0423 at $0.45 per million input tokens and $3.48 per million output tokens, which is a different route with its own retail schedule. (openrouter.ai)
How much does it cost to buy 1 million DeepSeek tokens?
One million DeepSeek-V4-Pro tokens does not have one price. On the direct API, one million off-peak cached input tokens costs $0.022, while one million peak output tokens costs $3.96. DeepSeek’s billing table separates those categories because processing new input costs more than reusing cached prompt text. (api-docs.deepseek.com)
A practical buyer should budget input and output separately. A short response can be cheap even when it reads a long prompt. A long generated report can cost more even when the input is small.
- Repeated system prompt: use the cache-hit price only after confirming your integration qualifies.
- Fresh document analysis: use the cache-miss input price because the document is new.
- Long generated answer: use the output price, which is the highest direct V4-Pro category.
How much cheaper is DeepSeek compared to OpenAI?
At the May V4-Pro output price of $0.87, DeepSeek was 91.3% cheaper than GPT-5’s $10 output rate cited at the time. The Next Web’s May comparison also put Claude Opus 4.7 output at $25 and Gemini 3.5 Flash output at $0.60 per million tokens.
That historical comparison needs a warning label.
It is also not a current competitor price check. DeepSeek’s present direct output rate is $1.98 off-peak, while those other figures were reported in May. Use the comparison to understand the old promotion, not to choose a provider today.
What does the current pricing cost in practice?
DeepSeek-V4-Pro becomes notably more expensive when an agent sends new context on every step. By our calculation, using DeepSeek’s published cache-miss and output prices, a 30,000-token prompt plus a 2,000-token answer costs $23.76 per 1,000 calls off-peak and $47.52 at peak.
Our calculation assumes no cache hits. It uses three simple workload profiles: a chat turn with 1,000 input and 500 output tokens; a document answer with 8,000 input and 500 output tokens; and an agent step with 30,000 input and 2,000 output tokens.
| Workload | Assumed tokens per request | Off-peak cost | Peak cost | Decision use |
|---|---|---|---|---|
| Short chat turn | 1,000 input + 500 output | $1.65 | $3.30 | Fine for low-volume support or internal chat. |
| Document answer | 8,000 input + 500 output | $6.27 | $12.54 | Schedule batch work outside peak windows. |
| Agent step | 30,000 input + 2,000 output | $23.76 | $47.52 | Cache tool instructions and route routine work carefully. |
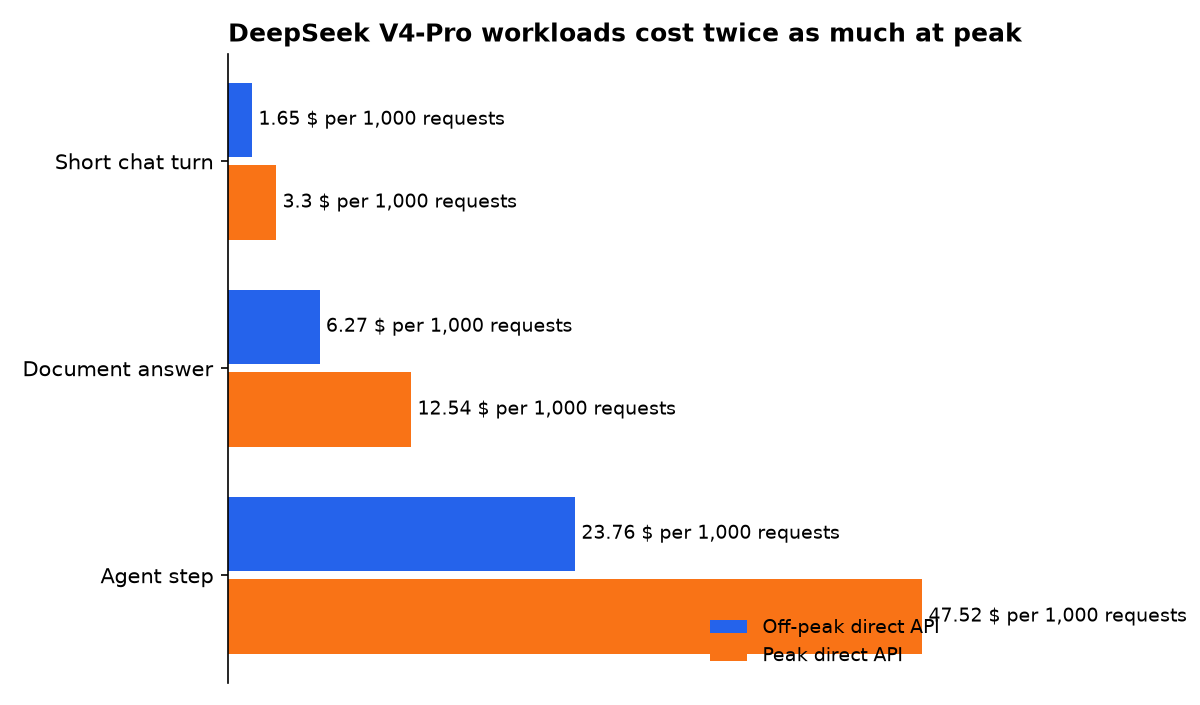
DeepSeek’s direct schedule says peak prices are exactly double off-peak prices. That means timing is a straightforward 50% saving when work can wait, but it does not restore the reported May rate. (api-docs.deepseek.com)
Is DeepSeek Pro a subscription price?
No verified subscription price follows from the V4-Pro API price cut. The official API page describes usage billing and says charges are deducted from a topped-up or granted balance, so these figures are metered API rates rather than a monthly “Pro” plan. (api-docs.deepseek.com)
That distinction matters for searchers looking for “DeepSeek Pro price.” A million tokens are not a consumer plan allowance. They are a unit of model use, similar to paying separately for the text sent to the model and the text it generates.
DeepSeek also lists Search and Fetch at $0.75 per 1,000 successful requests. The vendor says use through DeepSeek Harness, Claude Code or Codex is free until 1 November 2026, after which per-request billing starts. (api-docs.deepseek.com)
Which route should a buyer choose?
Choose DeepSeek’s direct API only after pricing your actual input, output and peak-hour mix. It is the only route here with an official current rate, a stated 1 million-token context limit and a published concurrency limit of 500 for V4-Pro. (api-docs.deepseek.com)
Choose a gateway only if its routing, account controls or provider choice justify a different retail price. OpenRouter’s model catalogue shows that DeepSeek offerings can appear with separate prices and model labels, so do not assume a “DeepSeek” gateway listing matches the direct API.
For routine work, schedule uncached bulk jobs off-peak and test caching. For sensitive workloads, price is only one input: data handling, contract terms and deployment location still need their own review. Enterprise DNA’s analysis correctly flags that the cache-hit rate can matter more than headline output prices for repeated agent prompts.
What we could not verify?
DeepSeek has not published a linked explanation on its current pricing page for why V4-Pro moved above the May permanent rates. Reuters’ syndicated report said the company did not disclose whether Huawei Ascend 950 chip supply was related to the original permanent cut.
No public direct statement in the pricing page maps the May V4-Pro rate to the current DeepSeek-V4-Pro-0813 schedule. DeepSeek could settle that question by publishing a dated price-change log and a version-by-version migration note.
There is also no verified consumer “V4-Pro subscription” price in the API material reviewed here. Buyers should treat $0.66 input and $1.98 output per million tokens as current direct off-peak API figures, then confirm the rate in their own account before committing production traffic.
Sources
- PRIMARY SOURCE — DeepSeek API Models Pricing
- Reuters — DeepSeek permanent V4-Pro price cut
- InfoWorld — V4-Pro price cut details
- The Next Web — May competitor price comparison
- OpenRouter — DeepSeek V4 Pro 0423 listing
- OpenRouter — Model catalogue
- Enterprise DNA — V4-Pro cache-price analysis
- Yahoo Finance / Reuters — DeepSeek price-cut report

